

Export External Database Tables
Description
Section titled “Description”Writes project tables into an external database through a connection, rather than to a file. Use it to push modelled results back into a reporting database, a data warehouse, or an operational system.
The mirror of Import External Database Tables: several tables move in one step, and the target tables can be selected explicitly or matched by a search pattern.
Unique Configuration Items
Section titled “Unique Configuration Items”Connection
Section titled “Connection”The data connection identifying the target database.
Export Type
Section titled “Export Type”How each target table is prepared before rows are written:
- Append Only — add rows to the existing table; fails if it does not exist.
- Truncate then Append — empty the table, keep its structure, then write.
- Create then Append — create the table if it is missing, then write.
- Drop, Create, then Append — drop and recreate the table, then write. Use when the source schema has changed.
Frame Name
Section titled “Frame Name”The name of the frame the step runs under.
Adding Targets
Section titled “Adding Targets”Use the add and remove target button to build the list of target tables. Select a target to configure it in the right pane, and use Toggle Selected to enable or disable the selected targets for export. Export does not scan the target database for tables; add each target yourself. Import External Database Tables is the step for discovering tables in an external database.
Target Tabs
Section titled “Target Tabs”A selected target has three tabs.
Source and Target
Section titled “Source and Target”Choose the project tables to export, and where they land.
- Source — Specific Table names one project table, with a Dynamic option for a name that changes at run time. Tables Matching Search exports every project table found by a Search Path and Search Text, matched as Exact, Starts With, Contains, or Ends With.
- Target External Table — Enable for export turns the target on or off. Target Schema and Target Table name the destination table. Use same name as source table reuses each source table’s name.
Table Data Selection
Section titled “Table Data Selection”The column mapper for the target, on its own full-height tab. Inspect Source reads the project source table’s columns into the mapper.
Data Filters
Section titled “Data Filters”Filter the rows written to the target.
Common Configuration Items
Section titled “Common Configuration Items”Data Mapper Configuration
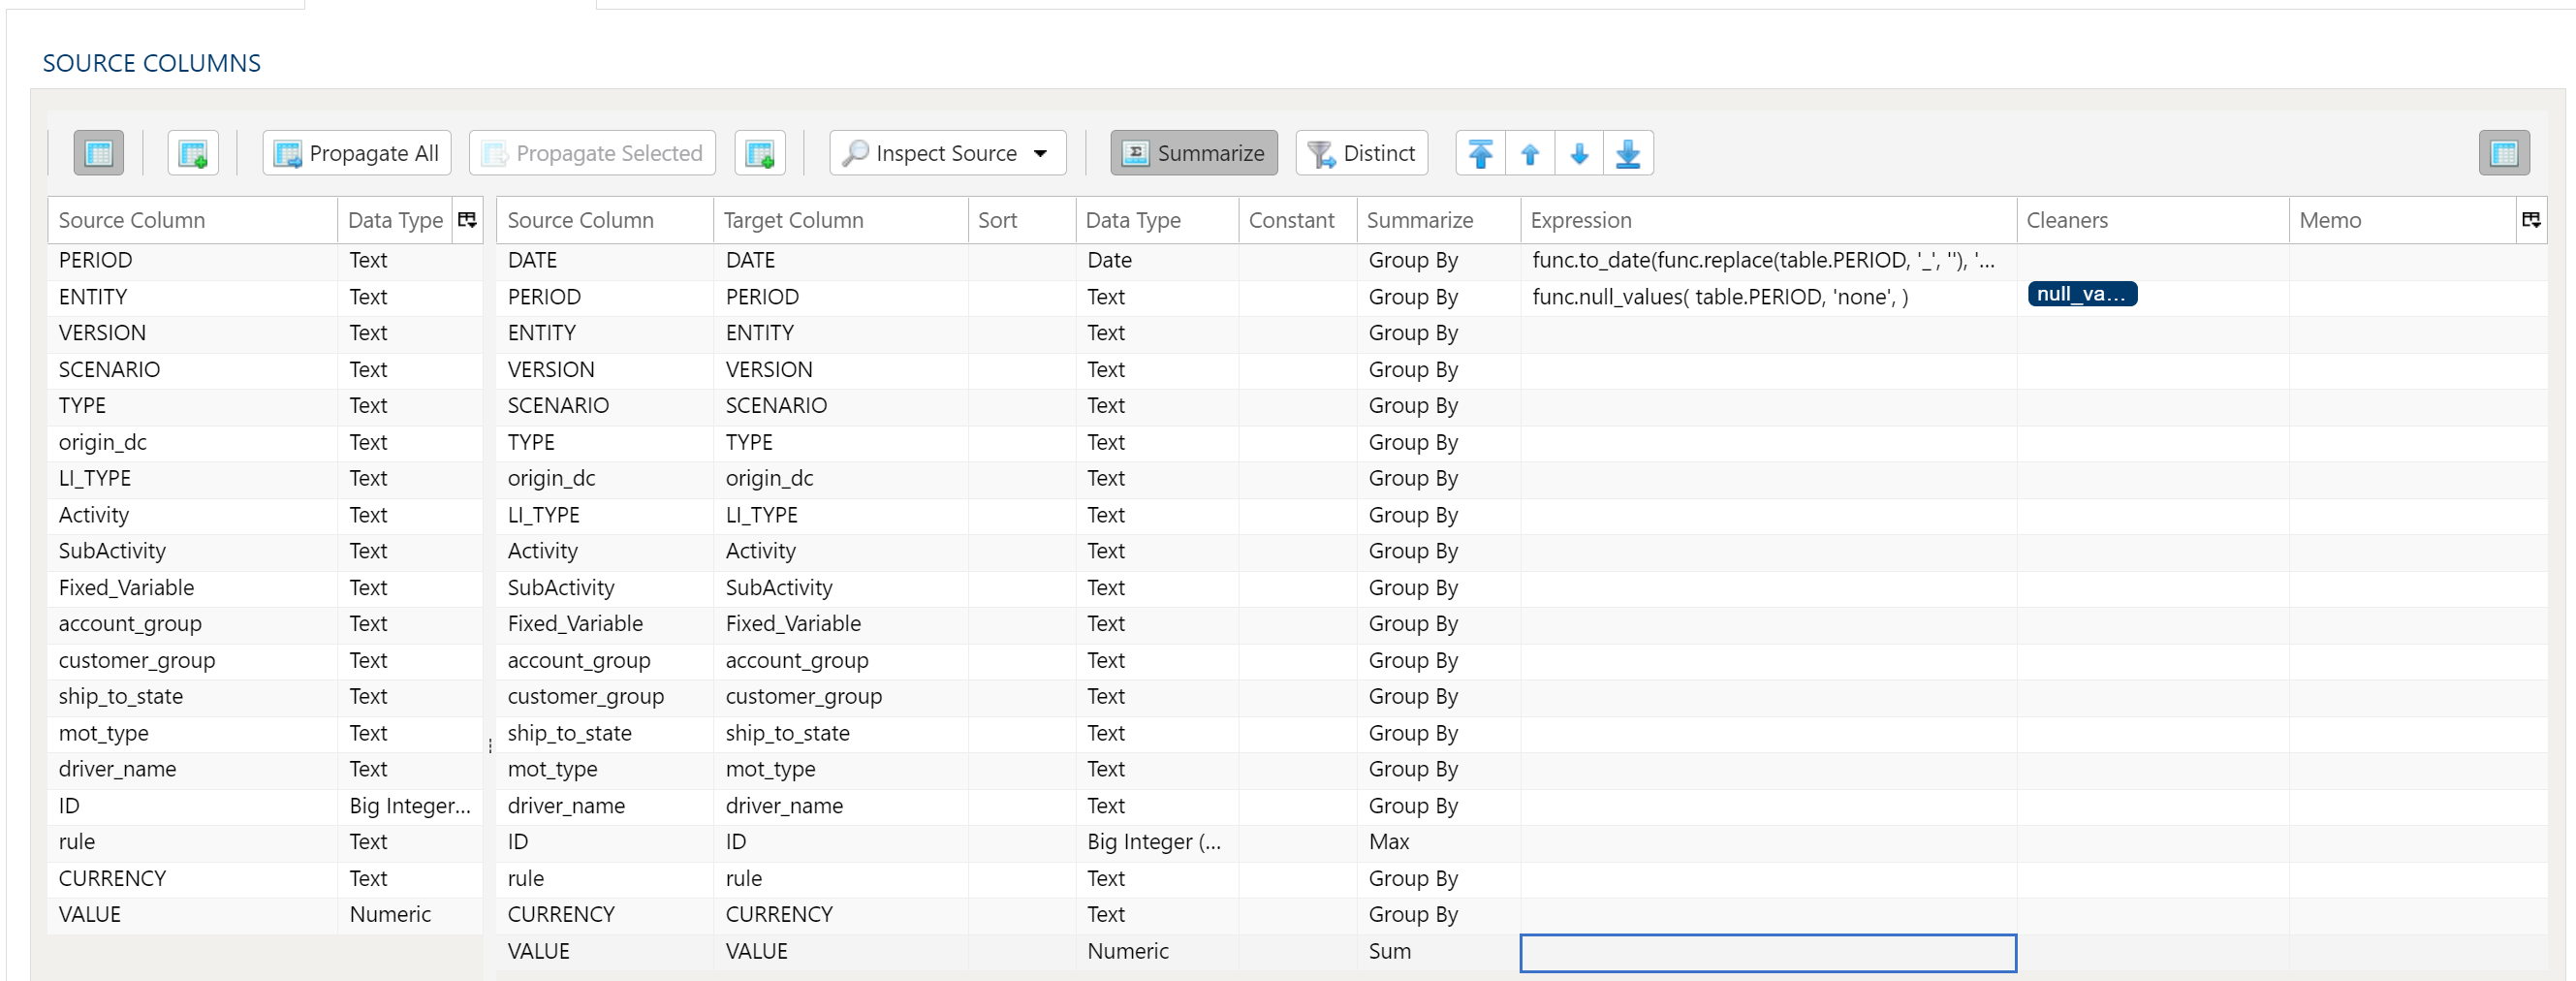
The Data Mapper is used to map columns from the source data to the target data table.
Inspection and Populating the Mapper
Using the Inspect Source menu button provides additional ways to map columns from source to target:
- Populate Both Mapping Tables: Propagates all values from the source data table into the target data table. This is done by default.
- Populate Source Mapping Table Only: Maps all values in the source data table only. This is helpful when modifying an existing workflow when source column structure has changed.
- Populate Target Mapping Table Only: Propagates all values into the target data table only.
If the source and target column options aren’t enough, other columns can be added into the target data table in several different ways:
- Propagate All will insert all source columns into the target data table, whether they already existed or not.
- Propagate Selected will insert selected source column(s) only.
- Right click on target side and select Insert Row to insert a row immediately above the currently selected row.
- Right click on target side and select Append Row to insert a row at the bottom (far right) of the target data table.
Deleting Columns
To delete columns from the target data table, select the desired column(s), then right click and select Delete.
Source Columns That Are No Longer Listed
A target row can name a Source Column that the source data table no longer lists, for example after the source was inspected again. The step never removes such a row for you. Instead, the column name is shown in red behind a ⚠ warning sign, and hovering over it says the column is not in the source columns. In a step with several tables, such as a union, each table is checked against its own source columns.
A row with a Constant, an Expression or a Count (including nulls) summary is never flagged, because the step doesn’t read its source column. Nothing is flagged while the source data table lists no columns, for example before the source is first inspected.
When you save a step that still has flagged rows, a Stale Columns Found dialog lists them under the tab or table they are on, and offers three choices:
- Remove All and Save — remove the flagged rows, then save.
- Save Anyway — save the step as it is.
- Cancel — go back to the step without saving.
To keep a row and clear its warning, add the column back to the source data table, or pick a column the source data table lists.
Column Data Type
Every target column carries a Type. A column propagated from the source keeps the source column’s type; a row you add by hand starts as Text, and you set Type to say what it should actually be — a column you intend to sum or sort needs its numeric or date type, because text sorts and sums as text.
A step saved with a column that has no type at all still runs. The type is worked out when the step starts, from the source column that column reads. Where there is nothing to read it from, it is treated as text: an Extract SQL step’s columns come from the query you wrote rather than from a mapped source, and where several sources carry the same column name under types that disagree, text is used rather than guessing one of them — a wrong guess produces a conversion the warehouse can reject, and anything converts to text.
Setting Type yourself is still how you say what a column should be. Leaving it unset means accepting whatever the source column happens to be.
Changing Column Order
To rearrange columns in the target data table, select the desired column(s). You can use either:
- Bulk Move Arrows: Select the desired move option from the arrows in the upper right
- Context Menu: Right clikc and select Move to Top, Move Up, Move Down, or Move to Bottom.
Reduce Result to Distinct Records Only
To return only distinct options, select the Distinct menu option. This will toggle a set of checkboxes for each column in the source. Simply check any box next to the corresponding column to return only distinct results.
Depending on the situation, you may want to consider use of Summarization instead.
The distinct process retains the first unique record found and discards the rest. You may want to apply a sort on the data if it is important for consistency between runs.
Aggregation and Grouping
To aggregate results, select the Summarize menu option. This will toggle a set of select boxes for each column in the target data table. Choose an appropriate summarization method for each column.
When Inspect Source fills the columns, a number column starts as Group By rather than Sum if its name reads as an identifier, such as id, customer_id, Order No or CustomerKey, if its table sets it as a key, or if the join uses it as a key.
- Group By
- Sum
- Min
- Max
- First
- Last
- Count
- Count (including nulls)
- Mean
- Standard Deviation
- Sample Standard Deviation
- Population Standard Deviation
- Variance
- Sample Variance
- Population Variance
- Advanced Non-Group_By
For advanced data mapper usage such as expressions, cleaning, and constants, please see the Advanced Data Mapper Usage

To allow for maximum flexibility, data filters are available on the source data and the target data. For larger data sets, it can be especially beneficial to filter out rows on the source so the remaining operations are performed on a smaller data set.
Select Subset Of Data
This filter type provides a way to filter the inbound source data based on the specified conditions.
Apply Secondary Filter To Result Data
This filter type provides a way to apply a filter to the post-transformed result data based on the specified conditions. The ability to apply a filter on the post-transformed result allows for exclusions based on results of complex calcuations, summarizaitons, or window functions.
Final Data Table Slicing (Limit)
The row slicing capability provides the ability to limit the rows in the result set based on a range and starting point.
Filter Syntax
The filter syntax utilizes Python SQLAlchemy which is the same syntax as other expressions.
View examples and expression functions in the Expressions area.